How Jev Works
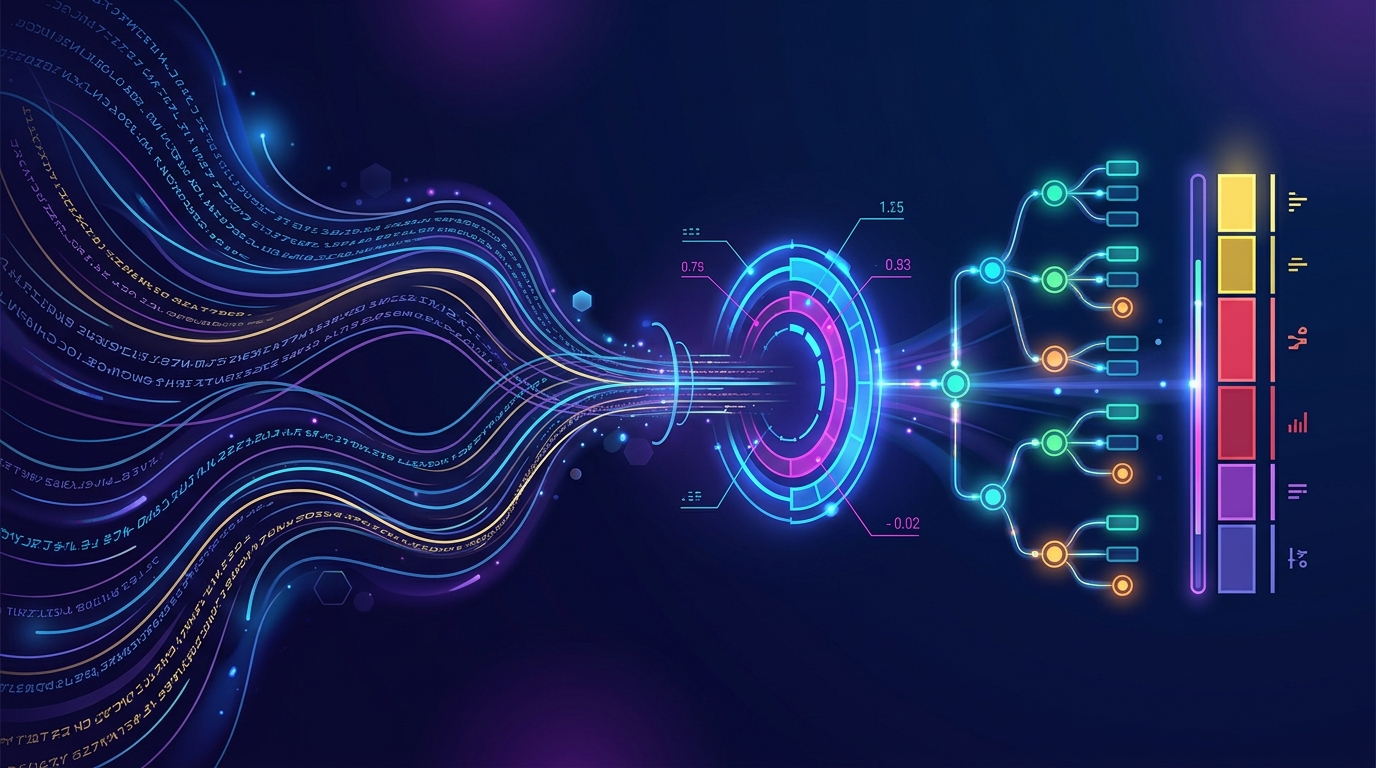
Jev is TypeSafe’s flagship System One model: instead of generating text, it evaluates a piece of content once and returns fast, typed, calibrated judgments your code can act on directly — probabilities, not prose.
This is the technical explainer. For the business case (accuracy, cost per decision, performance and integration with your existing systems), see Enterprise AI in Production (for CTOs) →
Typed judgments, not generated text
A normal LLM call answers in sentences you then have to parse. Jev instead takes a piece of state (your text, or structured data) and one or more questions about it, and returns a strict, typed answer for each — a probability, a selected option, or a position on a scale. There are three question types, called primitives:
Yes / no probability
Answers a single yes/no question with one number from 0 to 1 — the probability the answer is yes. No separate confidence value: for a binary outcome, one probability already describes the whole distribution.
“Does this message ask for a refund?” → 0.93
Pick one of a set
Selects one option from up to 255 you define, and returns the full probability distribution across all of them plus a confidence score describing how peaked that distribution is.
“Which team should this ticket go to?” → billing (0.81)
Position on a scale
Rates content against 2–10 ordered, concretely described levels, returning a probability-weighted score, per-level probabilities, and confidence.
“How severe is this bug?” → 1.43 / 2
One call, many judgments
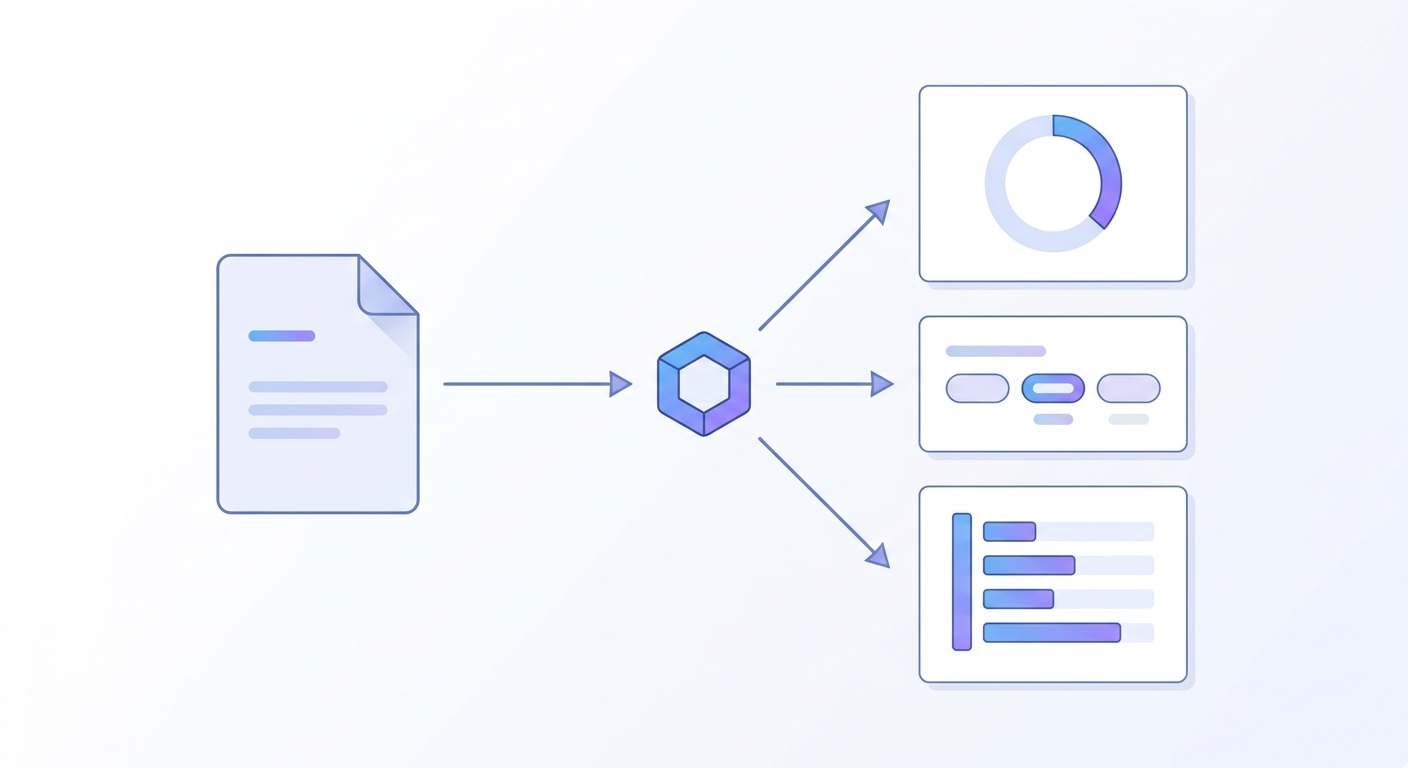
The real efficiency comes from batching: Jev evaluates the state once, then answers every question you attach to it in parallel, in the same request. Ask ten independent things about the same paragraph and you still pay for the state once. This is exactly what powers the live showcase below — every check you configure there runs against your text in a single call.
POST https://api.typesafe.ai/v1/systemone
{
  "model": "jev-latest",
  "state": "Can I please just talk to a real person?",
  "questions": {
    "wants_human": { "type": "noul", "instructions": "Does this message ask to speak to a human?" },
    "sentiment":   { "type": "score", "instructions": "How frustrated does the sender sound?",
                     "criteria": ["Calm", "Mildly annoyed", "Clearly frustrated"] }
  }
}
Confidence vs. probability
Probability is per-answer: how likely is “yes,” or how likely is each option/level. Confidence (on Choice and Score) is a separate 0–1 value describing how concentrated that distribution is — one clear winner gives high confidence, a near-even split gives low confidence, regardless of which option is ahead.
A practical rule of thumb: act automatically above ~0.9 confidence, confirm or gather more evidence between 0.5–0.9, and route to a human below 0.5 — then shift those thresholds based on how costly a wrong answer would be for that particular decision, not a single fixed number for the whole app.
Performance
TypeSafe’s documentation says most queries complete in about 100 ms, and in one of its published benchmarks an 8-question call averaged 114 ms round trip. There is no published SLA, so the showcase page also measures it for you: every run displays the real round-trip time for that exact request. The documented request limits that shape performance are:
Text-only input for now. English gets the strongest results; other languages, including CJK scripts, are supported with reduced accuracy.
Cost
Jev (model jev-1.13.0, aliased as jev-latest) is priced per input token, with output free:
Because batching means the state is only tokenized once per call, adding another check to the same content is cheap: you mostly pay again for that new question’s own instructions and criteria. A worked example — a 500-token piece of text plus five checks (roughly 150 tokens of instructions/criteria combined) is about 650 input tokens, or ≈ $0.000027 for that entire run. Try it yourself on the showcase page: every result shows the exact token count and cost for that run.
See it in action
Configure your own Noul, Choice and Score checks, describe what you want Jev to detect, and run them live against any text.
Try the live demo →